The prototype is not the product
Three days for a convincing demo, three months for a service you dare to connect to real data. Here is what fills those three months.
The first item is evaluation. Without a test set, there is no honest way to tell whether a change improves or degrades the system.
A demo is judged on ten questions chosen by the person presenting it. A production service receives thousands of questions nobody chose: misspelled, ambiguous, off-topic, sometimes malicious. The gap between the two is the whole job.
Build the evaluation set before anything else
We start every agent project with the same step, before writing a single final prompt: building an evaluation set. One to two hundred real cases, drawn from the requests the agent will have to handle, each with the expected answer or, failing that, the criteria for a good answer.
This set serves three purposes:
- To decide. Changing the model, rephrasing a prompt, adding a tool: every change is measured on the same set, and we keep whatever improves the score.
- To protect ourselves. A fix that solves one case often breaks three others. Without a test set, you only find out in production.
- To talk with the business. "87% correct answers on 150 representative cases" is a sentence a director can accept or reject. "It works pretty well" is not.
The set must include the difficult cases: ambiguous requests, out-of-scope ones, those where the right answer is "I don't know". An agent that answers everything confidently is more dangerous than an agent that knows when to stop.
Guardrails: deciding what the agent is not allowed to do
Unlike a simple chat assistant, an agent acts: it queries a database, sends an email, creates an order. Every tool you give it is an open door. So the question is not only "what should it do?" but "what must it be unable to do?"
- Minimal permissions. The agent connects with a dedicated account, read-only wherever writing is not essential.
- Human validation for irreversible actions. Sending, paying, deleting, publishing: the agent prepares, a human confirms.
- Explicit limits. Number of tool calls per request, maximum amount, closed list of recipients. An infinite loop costs money before it costs trust.
- Input filtering. A document or an email read by the agent may contain disguised instructions. What the agent reads is data, never an order.
Costs: what was negligible becomes a budget line
In a demo, the cost of a model call is invisible. In production, it is multiplied by the number of users, by the number of steps the agent chains together and by the length of the context sent at each step. An agent that rereads the whole conversation history at every turn sees its bill grow much faster than its usage.
Three habits keep this in check: measure the cost per request from day one, reserve the most powerful model for the steps that need it, and cache whatever repeats. The right indicator is not the monthly cost, it is the cost per successfully handled request.
Human supervision is not an admission of failure
Many projects aim for full autonomy from the start. It is the best way never to reach production. We prefer a gradual ramp-up:
- Suggestion mode. The agent proposes, a human validates every answer. We measure the acceptance rate.
- Supervised mode. The agent handles on its own the cases where it is confident; the others go to a human.
- Autonomous mode, on a limited scope, with sample-based checks.
Each step is taken on the strength of the numbers, not of an impression. And every correction made by a human enriches the evaluation set: supervision becomes the main source of improvement for the system.
Plan for the day the model does not answer
An AI service almost always depends on an external provider. That provider will have slowdowns, outages, rate limits, and it will change its models. Each of these events must have been anticipated:
- A maximum timeout for each call, beyond which the agent gives up cleanly rather than leaving the user waiting indefinitely.
- A degraded mode: passing the request to a human, or offering to try again later, with a clear message.
- A pinned model version, explicitly chosen. When the provider offers a new one, it goes through the evaluation set before being adopted, like any other update.
These are routine precautions for any software that depends on a third-party service. Yet they are almost always missing from prototypes.
See what is really happening
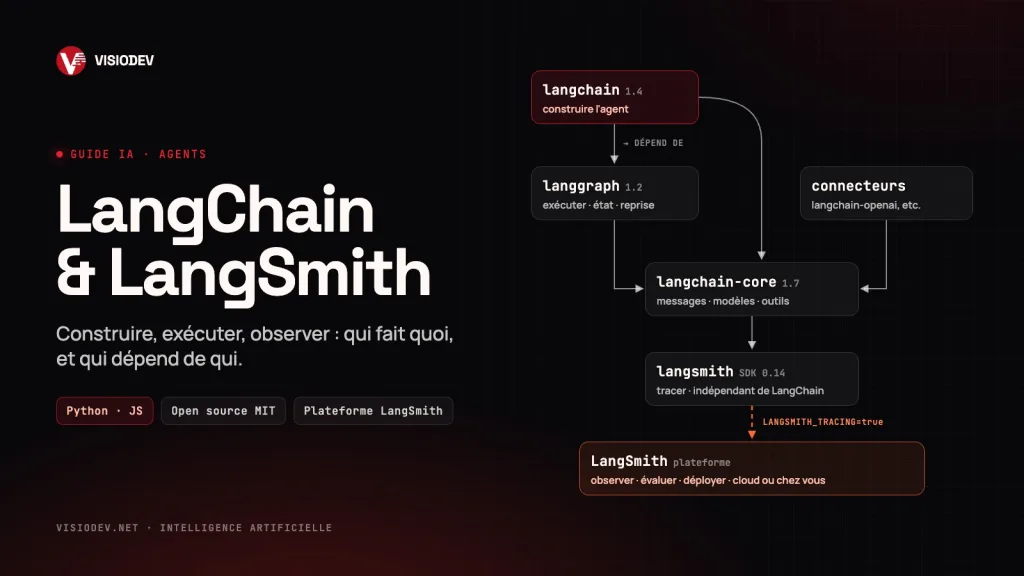
Finally, an agent in production must be observable. For each request, you need to be able to find what was received, the tools called, the responses obtained, the cost and the processing time. Without this trace, the slightest user complaint becomes an impossible investigation.
An AI agent is software like any other: it is tested, monitored and maintained. The magic stops at the demo.
If you have a prototype that works and you are hesitating to take the plunge, start with the simplest question: on how many real cases have you measured it?